From AI Pilot to Platform: How SMBs Scale the First Win
APR 27, 2026 9 MIN READ
The first AI agent works. The team trusts it. The numbers add up. The owner is asking what's next, and the answer is usually "the second agent". Then the third. Then the fourth.
Somewhere around agent three or four, the SMB hits a different problem than the one they had with agent one. The problem isn't whether AI can do the work. The problem is operational. Every agent has its own logging, its own deployment, its own way of tracking errors, its own prompt management. The team is spending more time maintaining the agents than building new ones. The fifth agent feels harder to ship than the first one did.
That's the moment to think about the pilot-to-platform transition. This post is how to do it well, in an SMB-budget-appropriate way, without falling into the "build a real MLOps platform" trap that consultants will sell you.
Why platforms come later than they look like they should
The temptation to build a platform on day one is real. Engineers like platforms. Vendors sell platforms. Conference talks recommend platforms. Most articles on AI scaling start with the platform.
This is backward for an SMB.
You don't know what the platform should do until you've shipped three or four agents. The patterns you'll standardize on are only visible after you've felt the pain of not standardizing. The eval method you'd build into the platform is different after agent three than it would have been after agent one. The prompt management approach that survives is the one that solved actual problems, not the one that was theoretically elegant.
So the right sequence is: ship one agent, ship a second one (probably copying patterns from the first), ship a third one (now noticing the duplicate work), then build a minimal platform that absorbs the duplicate parts.
Skipping ahead to "let's build a platform first" produces over-engineered systems that don't fit how the team actually works. I've seen it consume six months of an SMB's AI budget for no shipped agent. Wrong move.
What "platform" means in an SMB context
For a large company, platform means a real MLOps stack. Kubernetes orchestration, vector database clusters, fine-tuning pipelines, an internal developer platform, a model registry. None of this is what an SMB needs.
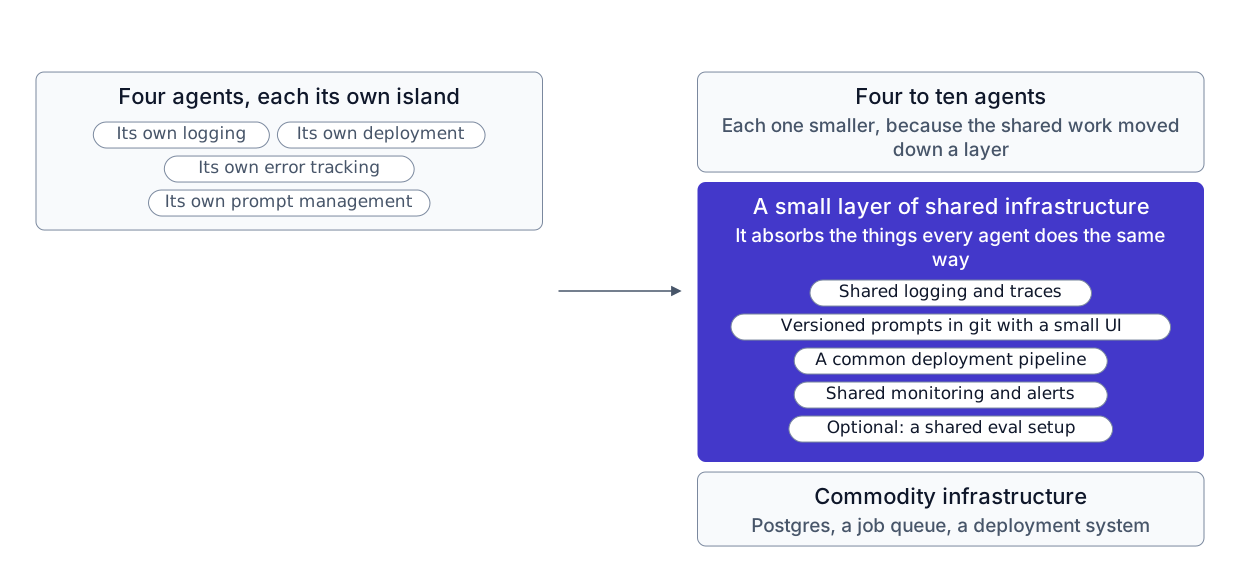
For an SMB running four to ten agents, platform means a small layer of shared infrastructure that absorbs the things every agent does the same way.
Shared logging and trace storage. Every agent should log inputs, outputs, model calls, latencies, and errors to a common store. So when something goes weird in week 12, you can pull the trace and figure out what happened.
A prompt management approach. Not a fancy system; a versioned git repo of prompts with a small UI for viewing them works. The point is to know which version of the prompt is in production for each agent and to be able to roll back.
A common deployment pipeline. Every agent should deploy through the same path. CI, environment promotion, basic canary if you can afford it. Saves an enormous amount of "how do I deploy this one again" cost.
Shared monitoring and alerts. One dashboard that shows the health of every agent. Error rate, latency, throughput, cost. Alerts when any agent crosses a threshold.
Optional: a shared eval setup. A way to define an eval set, run it on demand, compare model versions. This is the highest-value optional piece for SMBs and the one I recommend most often.
That's the whole platform. Five components. Probably 3,000 to 8,000 lines of code total. Most SMBs over-build this. Don't.
An original diagram, free to reuse with a link to this page · Download the SVG
The diagram as text
- Before: four agents, each with its own logging, its own deployment, its own error tracking and its own prompt management.
- After: four to ten agents on a small layer of shared infrastructure that absorbs what every agent does the same way: shared logging and traces, versioned prompts in git with a small UI, a common deployment pipeline, shared monitoring and alerts, and optionally a shared eval setup.
- Under it all: commodity infrastructure, Postgres, a job queue, a deployment system.
When to start the platform work
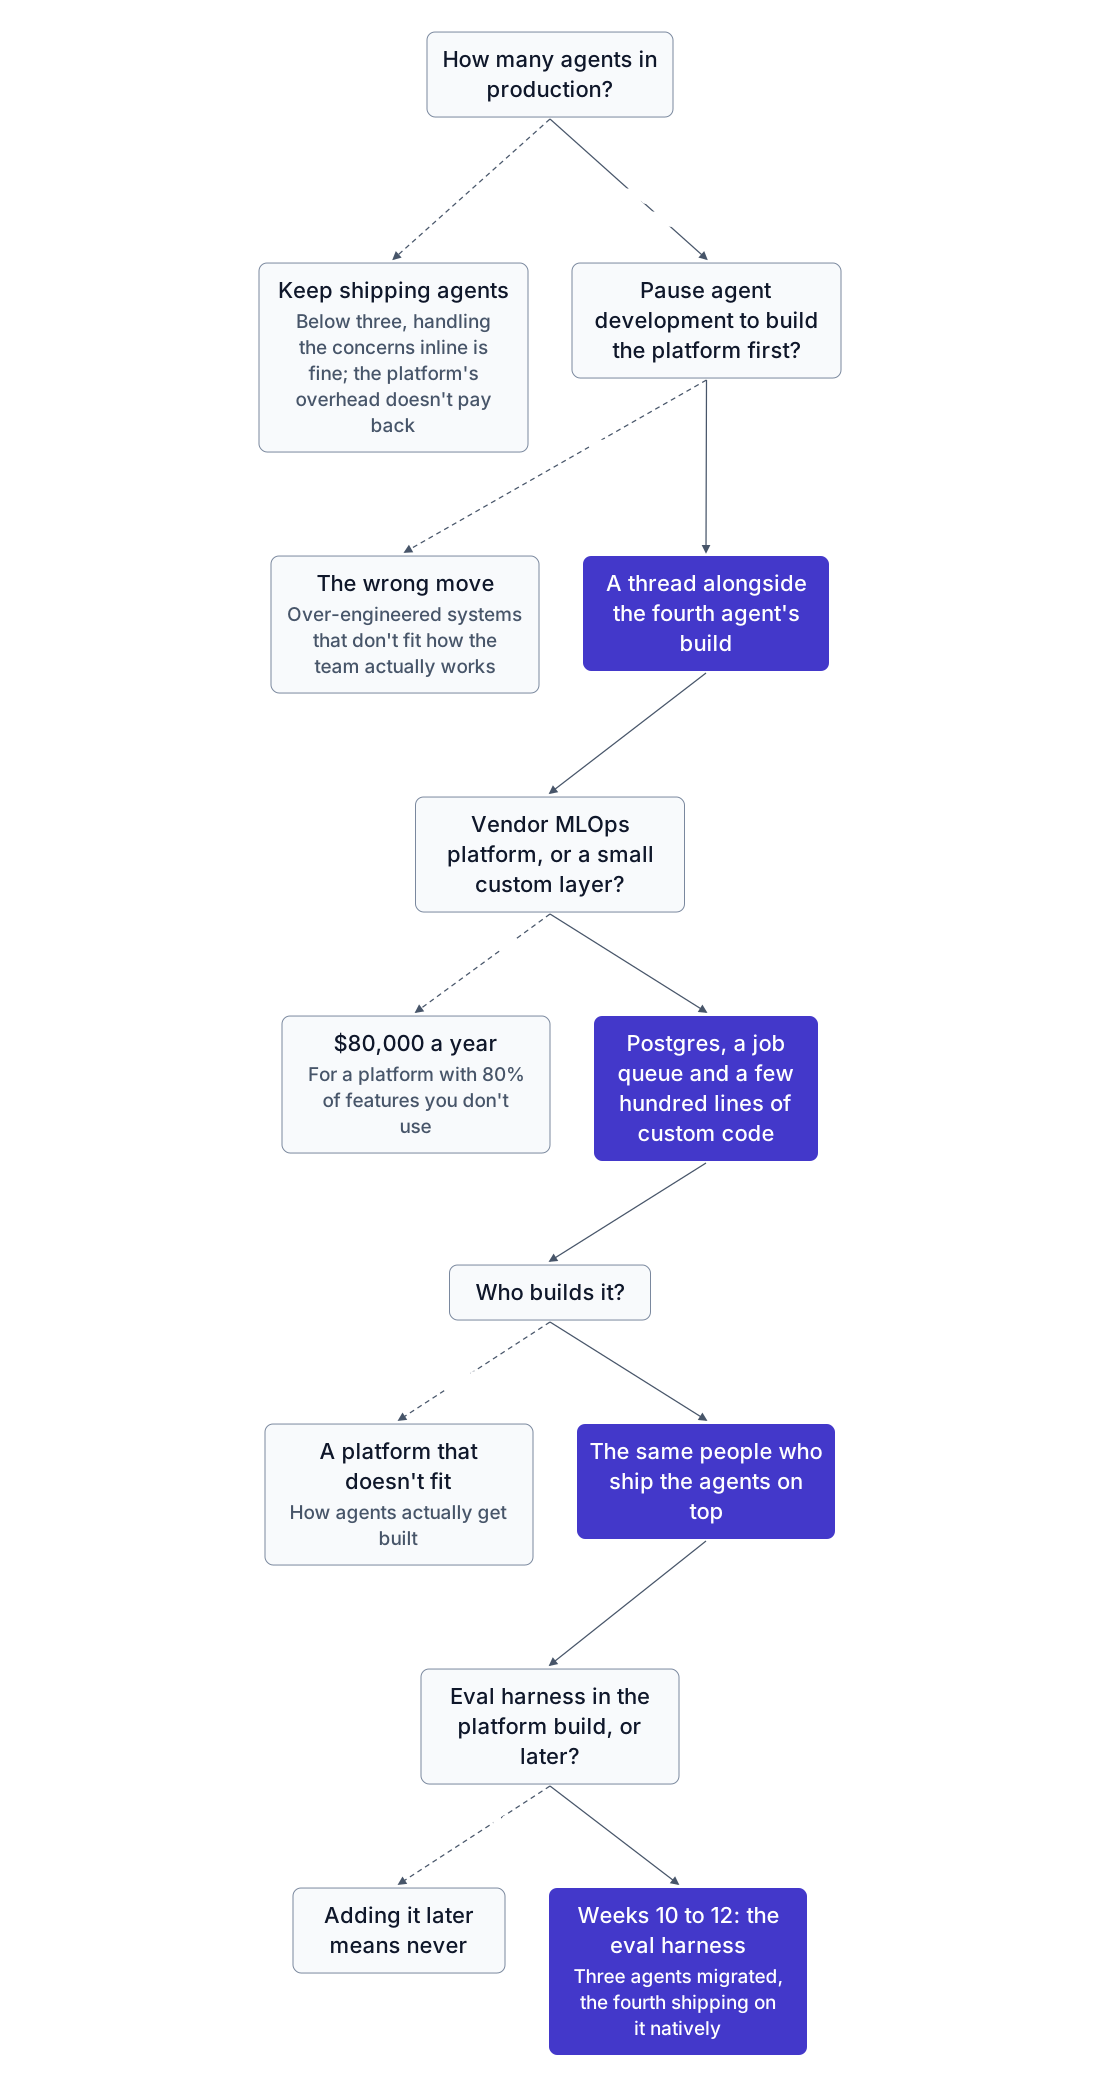
The trigger I use: when you have three agents in production and are starting the fourth.
Below three agents, the platform's overhead doesn't pay back. Each agent is small enough that handling its concerns inline is fine. Building the shared layer adds friction without enough volume to amortize.
At three agents, you're feeling the duplicate cost. The fourth agent will be the cheapest one to absorb the platform tax against. So plan the platform work as a thread that runs alongside the fourth agent's build, rather than as a standalone project.
Some SMBs over-engineer here too: they pause agent development to build the platform first. Wrong move. The fourth agent's build is what tells you which platform decisions are right. Build them together, even if the agent ships a bit slower as a result.
An original diagram, free to reuse with a link to this page · Download the SVG
The tree as text
- Below three agents in production, keep shipping: the platform's overhead doesn't pay back.
- At three and starting the fourth, don't pause agent development; run the platform as a thread alongside the fourth build.
- Pick a small custom layer on Postgres and a job queue over an $80,000-a-year vendor platform with features you won't use.
- The same people who ship the agents build it, and the eval harness goes in the build: adding it later means never.
Common platform mistakes I've watched SMBs make
A short list of the failure modes.
Building the platform before agent three. Already covered. The most common version.
Picking a vendor MLOps platform aimed at large companies. The price is wrong for an SMB, the feature set is overkill, and the integration cost is high. You end up paying $80,000 a year for a platform with 80% of features you don't use. The SMB-appropriate stack is usually built on Postgres, a job queue, and a few hundred lines of custom code.
Treating prompt management as a real software engineering problem. It usually isn't. Versioned text files in git plus a tiny UI is enough. The companies that build "prompt management platforms" want you to think otherwise because they're selling them.
Skipping the eval harness because "we'll add it later". Adding it later means never. The eval harness has to come in the platform build, otherwise no agent gets it.
Building the platform as a separate team's project. SMB platforms work when the people who build them are the same people who ship the agents on top. Outsourcing the platform to a separate team produces a platform that doesn't fit how agents actually get built.
A 12-week platform build for an SMB
If you're at the right stage (three agents in production, fourth in flight), a realistic platform build looks like this.
Weeks 1 to 2: audit the existing agents. Where are they duplicating work? Where do the patterns diverge in ways that matter? Pick the three to five biggest duplications to absorb into the shared layer.
Weeks 3 to 6: build the shared logging, trace storage, and basic monitoring. Refactor agent one to use it. This is the first real test that the platform works.
Weeks 7 to 9: build the deployment pipeline and prompt management. Refactor agents two and three.
Weeks 10 to 12: build the eval harness. Define eval sets for at least two of the existing agents. Wire alerts to the monitoring.
By week 12, you have a small platform, three agents migrated to it, and the fourth agent shipping on it natively. The fifth agent will be measurably faster to ship.
Budget: $30,000 to $80,000 depending on whether you're using internal engineers or a partner. Operating cost adds $200 to $800 a month for the shared infrastructure beyond what the individual agents were already costing.
This is much smaller than what large companies spend on AI platforms. That's the point. SMBs need a platform sized to their scale, not the one a Fortune 500 consultant would design.
What this enables
The boring promise of the platform is faster shipping for future agents. The fifth agent costs 30 to 50% less to ship than the first one did. The seventh costs 50 to 70% less.
The more interesting promise is operational visibility. After the platform is in place, you can answer the question "how is our AI program doing" with real numbers, not vibes. Total hours displaced, error rate trend, cost per inference, adoption rate by department. The platform is the layer that makes the AI program governable as a system, not as a stack of independent projects.
For SMBs that want a serious AI capability rather than a one-off project, this is the transition that matters. The first agent proves AI can work in your business. The platform proves you can scale it.
The owners I see do this well treat the platform as a normal piece of their roadmap, not as a separate workstream. I cover how to think about the broader roadmap elsewhere; the pilot-to-platform transition is the inflection point that the roadmap should plan for once you're past the first three builds.
RELATED READING
The AI Roadmap for Small Business: Start to Scale
Most small business owners I talk to are stuck in the same place with AI. They've watched ChatGPT do something impressive. They've signed up for two or three SaaS products with "AI" in the name.…
Custom AI Agents for Small Business: A Buyer's Guide
When SMB owners ask me about AI agents, the first thing I usually have to do is unscramble the word "agent". The term is used to mean five different things in five different vendor pitches, and most…
What It Really Costs to Build a Custom AI Agent in 2026
The cost to build a custom AI agent is the question SMB owners ask earliest and get the most varied answers on. I've seen quotes for "the same" agent range from $8,000 to $120,000 depending on who's…
Where to Start with AI in Your Business: A Guide
The question "where to start with AI in your business" is asked badly more often than it's asked well. I've heard it phrased as "what AI tool should we buy", "should we hire an AI person", "what's…
Why AI Projects Fail: A Pattern Guide for SMB Leaders
I've been on the receiving end of more failed AI projects than I'd like to admit. Some I ran. Some I inherited and tried to save. Some I was asked to do a post-mortem on after the original team had…
Product Roadmap Guide - Definition and Examples
Why are you building? What are you building? These two questions form the basis of any good product roadmap. Learn how to create the best product roadmap.
FREQUENTLY ASKED
- When should an SMB move from one-off agents to a platform?
- After the third agent ships and is in steady operation. Before that, you don't have enough patterns to design the platform around. After that, the cost of duplicate work and shared concerns (auth, logging, eval, prompt management) starts to outweigh the cost of building the platform layer.
- What's in an SMB AI platform?
- Less than vendors want you to think. A shared logging and eval store. A prompt management system (often just a versioned git repo of prompts with a small UI). A common deployment pipeline. Shared monitoring. Maybe a feature flag layer. That's it. You don't need a full MLOps stack.
- Build the platform or buy one?
- Mostly build, lightly. The off-the-shelf AI platforms are over-built for an SMB running four to ten agents. A small custom layer on top of commodity infrastructure (Postgres, a queue, a deployment system) wins. The exception is eval tooling, where buying makes more sense than building.